Detecting Evolutionary Shifts in Paleozoic Fish Jaw Shape with bifrost
Source:vignettes/jaw-shape-vignette.Rmd
jaw-shape-vignette.RmdIntroduction 🐠
This vignette demonstrates the core functionality of the
bifrost R package. bifrost
is designed to identify and analyze cladogenic shifts in multivariate
trait evolution. It is capable of analyzing morphological datasets
comprising thousands of species, without dimensionality reduction
techniques like PCA (see Uyeda, Caetano, and Pennell
2015).
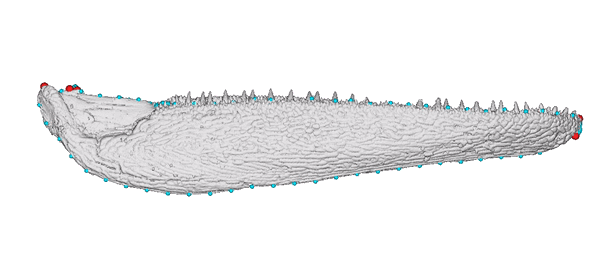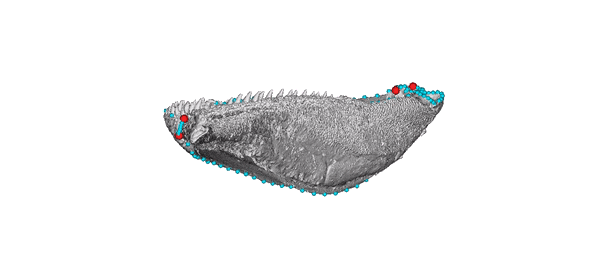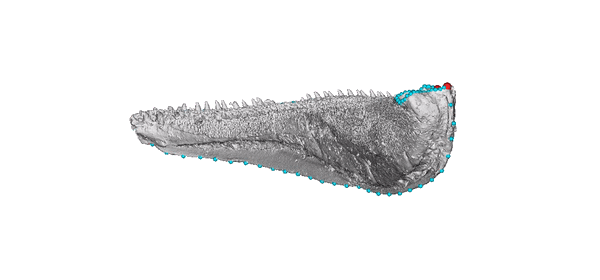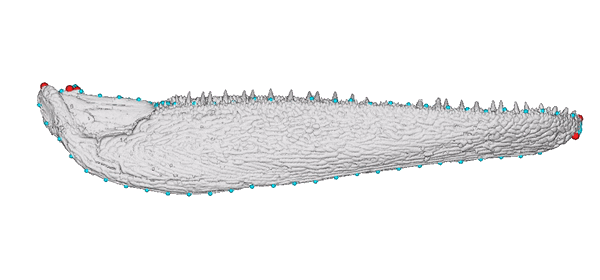
Figure 1. Animated jaw model of Gogosardina coatesi (specimen NMV P228269). The 3D model is publicly available on MorphoSource. The landmark scheme used in subsequent analyses includes six fixed points (red) and five curves (blue).
We will walk through an example using a fossil dataset from Troyer et
al. (2025), which examines macroevolutionary patterns of jaw shape
in the earliest radiation of bony fishes. bifrost
requires branch lengths to be expressed on a common scale, and does not
require ultrametric phylogenies.

Figure 2. Contrasting patterns of jaw-shape space exploration among early bony fishes. Phylogenetic traitgram of the first principal component (PC1) of lower jaw shape in early osteichthyans (bony fishes), from Figure 1 of Troyer et al. (2025). Learn more about Emily’s research here.
Troyer et
al. (2025) find that early lobe-finned fishes, such as lungfishes
and coelacanths, displayed surprisingly high rates of jaw evolution and
morphological diversity, while ray-finned fishes—a hyper-diverse group
today—showed much slower rates. This “macroevolutionary role reversal”
presents an interesting test-case for applying the
bifrost R package to infer shifts in the tempo and
mode of evolution across the phylogeny of early vertebrates.
We will use the primary function
searchOptimalConfiguration() to perform a greedy, step-wise
search to infer evolutionary regime shifts under multivariate Brownian
motion.
Setup
First, we load the bifrost package and other
necessary libraries for data manipulation and visualization.
# Load the search, phylogenetic, and landmark-shape dependencies.
library(bifrost)
library(ape)
library(phytools)
# geomorph is needed for two.d.array
# install.packages("geomorph")
library(geomorph)
Let’s load the data.
Loading the Data
The dataset consists of two main components:
- A phylogenetic tree (
mrbayes_prune_tree.RDS) for 86 species of Silurian-Devonian bony fishes. - A 3D landmark dataset (
jaws_coords.RDS) representing the 3D jaw shapes for each of these species.
On first use, bifrost_example_file() downloads
approximately 3 KB for the tree and 245 KB for the landmarks from the
maintained GitHub copy of the publication’s Dryad
dataset. Later calls reuse the verified local cache. To explicitly
check for an updated copy, run:
# Refresh the jaw tree only when an updated copy is wanted.
bifrost_example_file("jaw-tree", refresh = TRUE)
# Resolve the tree and landmark data through the public example-data cache.
tree_path <- bifrost_example_file("jaw-tree")
landmark_path <- bifrost_example_file("jaw-landmarks")

# Load the phylogenetic tree and landmark data
fish.tree <- readRDS(tree_path)
landmarks <- readRDS(landmark_path)

# Ensure the tree is in the correct format (a phylo object, here we also
# ladderize for downstream plotting)
fish.tree <- ladderize(untangle(as.phylo(fish.tree)))

# The raw landmark data is a 3D array (landmarks x dimensions x species) after
# GPA (Generalized Procrustes analysis)
# We convert the 3D array into a 2D matrix for analysis using a function from
# the geomorph package.
fish.data <- two.d.array(landmarks)

# It's crucial to ensure the order of species in the trait data matrix matches
# the order of tip labels in the phylogenetic tree.
tip_order <- match(fish.tree$tip.label, rownames(fish.data))
fish.data <- fish.data[tip_order, ]

# Let's inspect our data
print(fish.tree)
str(fish.data)
Running an example workflow
The core of the bifrost workflow is the
searchOptimalConfiguration() function. This function
automates the process of identifying the optimal placement of
evolutionary regime shifts on the tree.
Optional Runtime Setup
The next chunk is optional. It tweaks runtime behavior only: memory limits, an external plotting device for interactive live plots, and the session-level BLAS/OpenMP thread cap used by sequential linear algebra. None of these choices changes the model or search logic.
# ---- Optional: increase future globals limit (needed for large objects) ----
options(future.globals.maxSize = 10 * 1024^3)

# ---- Optional: open a dedicated plotting device for live search plots ----
# In RStudio, run this block before changing the search call to plot = TRUE if
# you want the live search tree to draw in an external graphics window.
if (interactive() && identical(Sys.getenv("RSTUDIO"), "1")) {
  if (.Platform$OS.type == "windows") {
    windows()
  } else if (Sys.info()[["sysname"]] == "Darwin") {
    quartz()
  } else {
    x11()
  }
}

# ---- Optional: speed up SEQUENTIAL linear algebra via BLAS/OpenMP threads ----
# NOTE: bifrost caps BLAS/OpenMP threads to 1 inside its PARALLEL blocks to
# avoid oversubscription.
thread_vars <- c(
  "OMP_NUM_THREADS", "OPENBLAS_NUM_THREADS", "MKL_NUM_THREADS",
  "VECLIB_MAXIMUM_THREADS"
)
old_threads <- Sys.getenv(thread_vars, unset = NA_character_)

n_threads <- "4"  # must be a character string
Sys.setenv(
  OMP_NUM_THREADS        = n_threads,
  OPENBLAS_NUM_THREADS   = n_threads,
  MKL_NUM_THREADS        = n_threads,
  VECLIB_MAXIMUM_THREADS = n_threads
)
The Function Call
Here is the function call we will use for this analysis. We’ll break down each parameter choice below.
The 54 random draws below reproduce the random-number state used for the cached 17-shift result, following thresholds 10 and 15 in the original threshold sweep.
# ---- Run the search ----
set.seed(1)
# Reproduce the RNG state preceding the cached threshold-20 search.
invisible(runif(54))
jaws_search <- searchOptimalConfiguration(
  baseline_tree              = fish.tree,
  trait_data                 = fish.data,
  min_descendant_tips        = 10, # try 4 for higher resolution (but more CPU time)
  num_cores                  = 4,
  shift_acceptance_threshold = 20,
  uncertaintyweights_par     = TRUE,
  IC                         = "GIC",
  plot                       = FALSE,
  formula                    = "trait_data ~ 1",
  method                     = "H&L", # penalized likelihood for high-dimensional data
  error                      = TRUE,
  store_model_fit_history    = TRUE,
  verbose                    = TRUE
)

# Restore environment variables if the optional thread block above was run
if (exists("old_threads", inherits = FALSE)) {
  for (nm in names(old_threads)) {
    val <- old_threads[[nm]]
    if (is.na(val) || val == "") {
      Sys.unsetenv(nm)
    } else {
      do.call(Sys.setenv, setNames(list(val), nm))
    }
  }
}
Understanding the primary input options
The table below gives a quick reference for the main choices made in this function call. The notes that follow focus on the rationale and caveats behind the less self-explanatory options.
| Option | Value here | What it controls |
|---|---|---|
baseline_tree |
fish.tree |
The starting phylogeny and single-regime null model |
trait_data |
fish.data |
The multivariate trait matrix analyzed by the model |
min_descendant_tips |
10 |
The minimum clade size considered for candidate shifts |
num_cores |
4 |
The number of CPU cores used to evaluate candidate shift models in parallel |
shift_acceptance_threshold |
20 |
The IC improvement required to accept a new shift |
uncertaintyweights_par |
TRUE |
Whether to estimate post-hoc support for accepted shifts in parallel |
IC |
"GIC" |
The information criterion used to compare candidate models |
plot |
FALSE |
Whether to enable the optional live SIMMAP display during the search |
formula |
"trait_data ~ 1" |
The multivariate GLS model structure |
method |
"H&L" |
The mvMORPH::mvgls fitting method |
error |
TRUE |
Whether to estimate and include measurement error |
store_model_fit_history |
TRUE |
Whether to write per-iteration model fits to temporary storage |
verbose |
TRUE |
Whether to print progress messages via
message() as candidates are generated and evaluated |
Some choices deserve additional context:
baseline_tree = fish.tree: Internally, all branches start in a single baseline regime (labeled “0”). The function searches for shifts away from this null model.trait_data = fish.data: These are the high-dimensional jaw shape coordinates modeled as the multivariate response.min_descendant_tips = 10: The initial candidate pool includes internal nodes with at least 10 descendant species. The filter is not reapplied after shifts are accepted, so nested shifts can leave fewer than 10 terminal tips assigned to a resulting regime. The appropriate candidate-size setting depends on the dataset.num_cores = 4: Whennum_cores > 1,bifrostusesfutureworkers for parallel candidate scoring and parallel IC-weight calculations. Only those future-based parallel blocks temporarily cap BLAS/OpenMP threads to 1 per worker to avoid CPU oversubscription, then restore the previous settings. Sequentialmvglsstages, such as the baseline fit and later greedy-search refits, use the BLAS/OpenMP settings already active in the R session; set those outside the search call if you want a higher cap for sequential linear algebra.shift_acceptance_threshold = 20: This is the core of the greedy algorithm. A potential shift is accepted only if it improves fit by at least 20 IC units (GIC units here), reducing the risk of spurious shifts.uncertaintyweights_par = TRUE: After the greedy search identifies an optimal shift configuration, the final model is refit repeatedly with each accepted shift removed in turn. The resulting IC weights quantify support for individual shifts in the context of the final model. The_parsuffix indicates that this step is done in parallel.IC = "GIC": The Generalized Information Criterion is generally preferred for high-dimensional data (like our landmark data) compared to alternatives like AIC or BIC.plot = FALSE: Live SIMMAP updates are disabled for this vignette run because they slow larger searches. Set this toTRUEfor small interactive tests; in RStudio, the optional graphics-device block above opens an external plotting window for those updates.formula = "trait_data ~ 1": The intercept-only model (~ 1) corresponds to a multi-rate Brownian Motion process where each regime has its own rate matrix. The GPA-aligned morphometric coordinates are already size and rotation adjusted, so no additional size term is needed here. For linear dimensions or other predictors, you can use formulas that reference subsets oftrait_data, for example"trait_data[, 1:5] ~ 1"to treat columns 1–5 as the multivariate response, or"trait_data[, 2:ncol(trait_data)] ~ trait_data[, 1]"if the first column is log-mass and the remaining columns are logged linear dimensions. For a formula with predictors, choose a fitting method supported for that design. InmvMORPH,method = "H&L"is intended for intercept-only models.method = "H&L": H&L is a fast, approximated leave-one-out cross-validation (LOOCV) approach based on Hoffbeck and Landgrebe (1996). It is effective for intercept-only models with a “RidgeArch” default penalty, making it a reasonable choice for this high-dimensional dataset. The high-dimensional penalized likelihood framework used bymvMORPH::mvglsis described by Clavel, Aristide, and Morlon (2019). Other options passed tomvglswill depend on the nature of the input dataset.error = TRUE:mvglsestimates a measurement-error (intra-specific variance) term and incorporates it into the model. Even without explicit measurement-error values, the function treats this variance as an additional parameter, which is recommended for empirical datasets with within-species variation.store_model_fit_history = TRUE: Write per-iteration model fits to a temporary directory (tempdir()) during the search to avoid inflating memory usage while computation is ongoing; the full model-fit history is read back into memory at the end of the search.
Checking numerical stability
The seed and preceding random draws in the call above reproduce the documented random-number setup for the cached example. Reproducing one run does not by itself assess sensitivity to initialization or establish that its numerical fits reached the best solution.
For conclusions that depend on individual shifts, repeat the search with the same data, tree, formula, and search settings using several recorded seeds when initialization is stochastic. Save the results and compare accepted nodes, GIC values, and fitted rates. Inspect optimizer codes and messages for the final model and saved forward proposals when available. A code of 0 does not guarantee a global optimum, and different seeds may produce the same starting values. Full searches and drop-one support calculations can be computationally expensive.
jaws_search$model_no_uncertainty$opt[c("convergence", "message")]The saved forward-fit history does not include the initial candidate-scoring fits. Per-shift IC weights describe support conditional on the selected fitted model; they are not a check of numerical convergence or alternative search paths.
Interpreting the Output
Figures 3–5 show the cached threshold-20 result from the threshold sweep. The
selected model retained 17 shifts and improved the GIC by more than
7,000 units relative to the single-regime baseline. The sweep cache
contains the fitted model and VCVs but omits proposal history and
drop-one support weights. Figure 4 uses a separately cached reproduction
with proposal history: its accepted nodes, fitted rates, and VCV values
match the sweep result, and its final GIC agrees to within
1e-7. The call above saves history and requests support
weights so that both diagnostics are available when running the example
yourself.
| Result | Value |
|---|---|
| Accepted shifts | 17 |
| Accepted shift nodes | 107, 113, 115, 94, 128, 129, 158, 157, 98, 161, 92, 89, 93, 96, 97, 108, 116 |
| Baseline GIC | -335266.29 |
| Optimal GIC | -342739.42 |
GIC improvement
(baseline_ic - optimal_ic) |
7473.13 |
The searchOptimalConfiguration() result is a named list.
These are the main components to inspect first:
| Component | Interpretation |
|---|---|
shift_nodes_no_uncertainty |
Integer node numbers where shifts were accepted in the selected no-uncertainty configuration |
baseline_ic and
optimal_ic
|
GIC scores for the single-regime baseline and selected multi-regime model; lower IC is better |
VCVs |
Regime-specific variance-covariance matrices, including
the baseline regime "0"
|
ic_weights |
Drop-one support values for individual shifts when
uncertaintyweights_par = TRUE
|
model_fit_history |
Per-iteration model fits used by
icTrajectory() to diagnose search behavior |
# The bifrost_search object has a custom S3 print method:
# typing the object shows a summary.
jaws_search
Let’s look at the key components programmatically:
# The node numbers where shifts were inferred and accepted
print(jaws_search$shift_nodes_no_uncertainty)

# The final, optimal IC score compared to the baseline
cat("Baseline GIC:", jaws_search$baseline_ic, "\n")
cat("Optimal GIC:", jaws_search$optimal_ic, "\n")
cat("Improvement (Delta GIC):", jaws_search$baseline_ic - jaws_search$optimal_ic, "\n")

# The VCV matrices contain estimated rates and covariances for each regime.
# The root regime is always assigned to `0`.
dim(jaws_search$VCVs$`0`)

# The ic_weights sub-object stores detailed information about shift support
# if uncertaintyweights_par = TRUE.
print(as.matrix(jaws_search$ic_weights))

# Extract the strongest-supported shift nodes and corresponding IC weights
support <- jaws_search$ic_weights[order(
  jaws_search$ic_weights$ic_weight_withshift,
  decreasing = TRUE
), c("node", "ic_weight_withshift")]
print(head(support, 10))

# Extract the nodes with weights > 95%
print(with(jaws_search$ic_weights, {
  sel <- ic_weight_withshift > 0.95
  cbind(node = node[sel], weight = ic_weight_withshift[sel])
}))
# Display root-regime correlations using the manuscript's color scale.
correlation_palette <- grDevices::colorRampPalette(c(
  "#313695", "#4575B4", "#74ADD1", "#ABD9E9", "#E0F3F8",
  "#FFFFFF", "#FEE090", "#FDAE61", "#F46D43", "#D73027", "#A50026"
))(201L)
correlation_breaks <- seq(-1, 1, length.out = length(correlation_palette) + 1L)
old_par <- par(no.readonly = TRUE)
heatmap(
  cov2cor(jaws_search$VCVs$`0`), scale = "none", labRow = "", labCol = "",
  margins = c(6, 0), col = correlation_palette, breaks = correlation_breaks
)
# Draw a labeled color scale in the bottom margin.
par(fig = c(0.25, 0.80, 0.01, 0.10), mar = c(0, 0, 0, 0), new = TRUE, xpd = NA)
plot.new()
plot.window(xlim = c(-1.1, 1.1), ylim = c(0, 1), xaxs = "i", yaxs = "i")
rect(correlation_breaks[-length(correlation_breaks)], 0.40,
     correlation_breaks[-1L], 0.62, col = correlation_palette, border = NA)
rect(-1, 0.40, 1, 0.62, border = "grey30")
text(c(-1, 0, 1), 0.18, labels = c("-1", "0", "1"), cex = 0.8)
text(0, 0.90, labels = "Evolutionary correlation (r)", cex = 0.85)
par(old_par)
Figure 3. Estimated evolutionary correlations for the root regime. Heatmap of estimated evolutionary correlations (computed as
cov2cor(jaws_search$VCVs$`0`)) among jaw-shape traits for the root regime in the cached 17-shift model. Rows and columns are hierarchically clustered, with no row standardization of the correlations. Colors range from blue for negative correlations to red for positive correlations. Blocks of high correlation along the diagonal may indicate modular patterns of trait evolution.
Inspecting the search behavior
# Since we saved the model search history

# We can inspect the behavior of the search with an IC trajectory.
op <- par(oma = c(0, 0, 1.5, 0)) # leave room for the title on file devices
plot(
  icTrajectory(jaws_search),
  delta_limits = c(6000, -3000), # include the first improvement; leave legend space
  scales = c(point = 1.30, line = 1.25, text = 1.15),
  point_sizes = c(accepted = 1.82, rejected = 1.30),
  line_widths = c(running_best = 2.52, rejected = 3.17),
  text_sizes = c(
    main = 1.45,
    x_axis = 1.22,
    axis_label = 1.34,
    y_axis = 0.94,
    delta_axis = 0.94,
    annotation = 1.20,
    legend = 1.15
  ),
  annotation = c(baseline_label_offset = 2.05)
)
par(op)
Figure 4. Information-criterion trajectory for the 17-shift jaw-shape search. Of 28 sequential proposals, 17 were accepted (blue points) and 11 rejected (red crosses). The blue step line tracks the running best GIC, and the black point marks the baseline. The gray line shows proposal-level delta GIC on the right axis, with positive improvements drawn downward; an improvement below the 20-unit acceptance threshold is rejected. Labels mark the baseline (−335266.29) and final minimum accepted GIC (−342739.42). The delta axis includes the first improvement of about 5199 units.
Generating a branch-rate plot
# Rank branch rates with viridis: dark purple = slow, yellow = fast.
cols  <- generateViridisColorScale(jaws_search$model_no_uncertainty$param)$NamedColors
rates <- jaws_search$model_no_uncertainty$param[names(cols)]

plotSimmap(
  jaws_search$tree_no_uncertainty_untransformed,
  ftype = "off",
  direction = "upwards",
  colors = cols
)

# ---- Ranked color key (bottom-left, inside plot region) ----
op <- par(xpd = NA)
usr <- par("usr"); xr <- diff(usr[1:2]); yr <- diff(usr[3:4])

# Geometry (fractions of plot range)
x0 <- usr[1] + 0.05 * xr
x1 <- x0 + 0.70 * (0.30 * xr)
y0 <- usr[3] + 0.06 * yr
y1 <- y0 + 0.512 * (0.06 * yr)

vscale <- 0.64
cols_ord <- cols[order(rates)]
xs <- seq(x0, x1, length.out = length(cols_ord) + 1L)

rect(xs[-length(xs)], y0, xs[-1], y1, col = cols_ord, border = NA)
rect(x0, y0, x1, y1, border = "grey30")

text((x0 + x1) / 2, y1 + vscale * (0.03 * yr),
     "Rate rank (slow to fast)", cex = 0.9)
par(op)
Figure 5. Branch-rate visualization for the cached 17-shift model. SIMMAP-style phylogeny with branches colored by the rank of their fitted regime rate. Colors are evenly spaced along the viridis palette from dark purple (slowest) to yellow (fastest); color distances do not encode differences in rate magnitude. Faster branches on the left side correspond to Dipnoi – or lungfish; see Troyer et al. (2025).
Conclusion
This vignette demonstrates how to use bifrost to explore
rate shifts in a high-dimensional jaw-shape dataset. The cached search
selects candidate shifts under the stated GIC threshold and estimates
regime-specific VCVs. Their interpretation depends on the model and
search settings and should be accompanied by numerical and
setting-sensitivity checks. For branch-rate summaries and threshold
sensitivity in this dataset, continue to the rate-map jaw-shape
vignette.
References
- Clavel, J., Aristide, L., and Morlon, H. (2019). A Penalized Likelihood Framework for High-Dimensional Phylogenetic Comparative Methods and an Application to New-World Monkeys Brain Evolution. Systematic Biology, 68(1), 93-116. https://doi.org/10.1093/sysbio/syy045
- Hoffbeck, J. P., and Landgrebe, D. A. (1996). Covariance Matrix Estimation and Classification with Limited Training Data. IEEE Transactions on Pattern Analysis and Machine Intelligence, 18(7), 763-767. https://doi.org/10.1109/34.506799
- Troyer, E. M., Rivero-Vega, R. A., Cui, X., Zhu, M., Qiao, T., Saad, H. H., Figueroa, R. T., Andrews, J. V., Clement, A. M., Lebedev, O. A., Higgins, R. R., Igielman, B., Pierce, S. E., Giles, S., and Friedman, M. (2025). Macroevolutionary role reversals in the earliest radiation of bony fishes. Current Biology, 35(19), 4631-4641.e3. https://doi.org/10.1016/j.cub.2025.08.008
- Uyeda, J. C., Caetano, D. S., and Pennell, M. W. (2015). Comparative Analysis of Principal Components Can Be Misleading. Systematic Biology, 64(4), 677-689. https://doi.org/10.1093/sysbio/syv019
Software Used in This Vignette
-
bifrostfor the shift search, IC-trajectory extraction, and branch-rate color helpers. - Clavel, J., Escarguel, G., and Merceron, G. (2015). mvMORPH: an R package for fitting multivariate evolutionary models to morphometric data. Methods in Ecology and Evolution, 6(11), 1311-1319. https://doi.org/10.1111/2041-210X.12420
- Baken, E. K., Collyer, M. L., Kaliontzopoulou, A., and Adams, D. C. (2021). geomorph v4.0 and gmShiny: enhanced analytics and a new graphical interface for a comprehensive morphometric experience. Methods in Ecology and Evolution, 12(12), 2355-2363. https://doi.org/10.1111/2041-210X.13723
- Adams, D. C., Collyer, M. L., Kaliontzopoulou, A., and Baken, E. K. (2025). Geomorph: Software for geometric morphometric analyses. R package version 4.0.10. https://CRAN.R-project.org/package=geomorph
- Paradis, E., and Schliep, K. (2019). ape 5.0: an environment for modern phylogenetics and evolutionary analyses in R. Bioinformatics, 35(3), 526-528. https://doi.org/10.1093/bioinformatics/bty633
- Revell, L. J. (2024). phytools 2.0: an updated R ecosystem for phylogenetic comparative methods (and other things). PeerJ, 12, e16505. https://doi.org/10.7717/peerj.16505